
Monitoring, incident management and operational decisions in AI-supported core processes require a clear separation of responsibilities. IT or a managed services partner must take technical system ownership, while the business unit is responsible for functional process ownership. This ensures that IT focuses on infrastructure stability and the business unit on accepting process outcomes.
Ownership of AI continuity in core processes
This article addresses the need for a structured approach to ownership in AI-supported core processes, in which technical and functional responsibilities are clearly separated.
- Technical system ownership should sit with IT or a managed services partner to ensure infrastructure stability.
- Functional process ownership should sit with the business unit for substantive acceptance criteria.
- AI incident management requires extensive telemetry to trace the cause of quality degradation.
- A clear escalation route should lead to decisions about continuing AI processes.
Who is responsible for AI continuity in core processes?
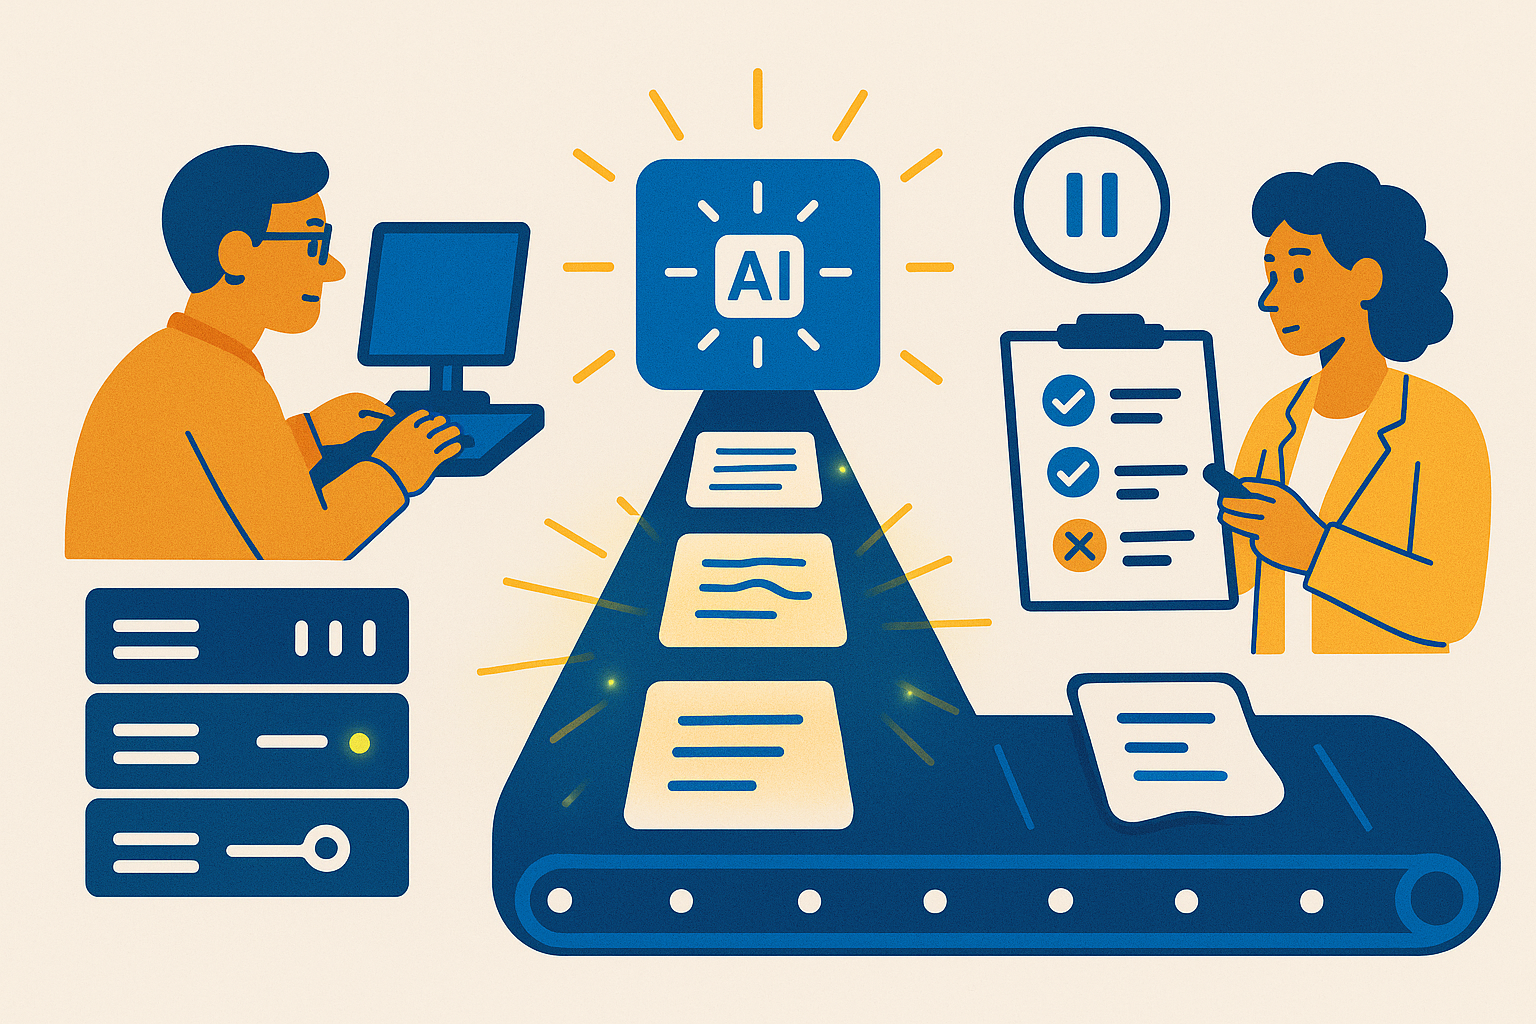
AI continuity requires two explicitly distinct forms of ownership. Technical system ownership rests with IT or a managed services partner. This includes the stability of the underlying application and the technical signals that show whether the service remains available and executable. Functional process ownership rests with the business unit responsible for the process outcome. That party therefore determines not only whether an outcome has been delivered technically, but also whether it substantively falls within the agreed acceptance criteria.
This division prevents a quality issue from being passed between teams. IT may establish that an integration is responding and that technical components are available, while the business unit sees that the generated content is no longer usable for the process. Both observations can be true at the same time. By separating the roles, it becomes clear who answers which question: IT handles system stability; the business unit accepts, rejects or corrects the meaning of the AI output.
The degree of autonomy determines how sharply this boundary must be drawn. When AI only provides draft proposals that an employee reviews, human validation remains part of the process step. When AI independently posts transactions, considerably stricter programmatic validation layers and hard backend limits are required. In both situations, the business owner remains the appropriate role to assess acceptance of outcomes, but the consequences of that assessment differ substantially. In autonomous processing, the issue is not only an incorrect proposal, but processing that has already had an effect within the process.
A designated business owner therefore also needs a concrete power to intervene: the ability to temporarily switch off the AI subsystem when substantive quality is no longer acceptable. This is not a technical assessment of the cause, nor is it a replacement for IT ownership. It is a process decision to stop further unsuitable output while investigation and recovery take place. Without this authority, a technically available system can continue producing undesirable process outcomes because nobody can formally decide to halt the AI step.
Continuity also includes what happens after launch. Changing input behaviour can cause quality degradation that is not identified in time without fixed golden datasets and automated regression tests. The technical owner can support these checks; the functional owner determines which outcomes form the reference and when deviation is no longer acceptable. This links ownership to the actual responsibility for both infrastructure stability and process quality.
Sources for this section: NIST AI Risk Management Framework (AI RMF 1.0)
Why traditional incident management falls short for AI workflows
Traditional incident management is generally designed for technical deviations that can be clearly recognised: an error status, an unavailable service or processing that stalls. In an AI workflow, however, the technical chain can return a successful response while the substantive outcome differs from what the process requires. An HTTP 200 status then indicates that a response was returned, not that the response is substantively correct, complete or usable. This creates a different category of incident: silent quality degradation that is not visible in technical signals alone.
A possible sequence illustrates why this is operationally challenging. An external LLM provider may implement a model change. The integration continues to respond, but the meaning of the output shifts slightly. If IT only tracks HTTP 200 statuses, this change remains out of sight. In the described scenario, this leads to incorrectly generated volume discounts being written to an ERP system. Complaints about incorrect invoices only follow after the incorrect output has already had process consequences. This creates not only recovery work, but also uncertainty between operations, IT and the external software partner about who should have intervened.
AI incident management therefore needs information that connects the technical event to the substantive outcome. For every AI decision point, extensive telemetry can record payload parameters, prompt versions, model embeddings and confidence scores. In the event of quality degradation, this record makes it possible to investigate whether changed source data, an external LLM update or integration logic is the cause. This is a different starting point from merely establishing that an integration is reachable: the investigation focuses on the traceability of a decision used within a business process.
Service agreements consequently also change in nature. A Service Level Agreement that addresses only hosting uptime does not automatically cover a quality regression in AI output. In this situation, agreements can include, alongside availability, response times for AI-specific quality regressions, prompt maintenance and periodic evaluations. This establishes in advance that a substantive deviation can be handled as an operational event, even where there is no classic technical error message.
If nobody on the business side is authorised to temporarily disable the AI component, the process can continue with deviating output while teams are still investigating what has changed. With incorrect invoices, the consequences then accumulate instead of the incident response limiting further processing.
Sources for this section: NIST AI Risk Management Framework (AI RMF 1.0)
When is ownership of AI continuity crucial?
The pressure on ownership increases as soon as AI no longer merely produces a supporting proposal, but forms a link in the progress of a core process. This applies in particular when a process becomes dependent on an external AI provider. A model change or a limit on the number of permitted requests can then directly affect the process if no modular abstraction layer or proxy is present around public AI APIs. The dependency is then not merely commercial or technical; it determines whether the process can continue to function after an external change.
In this situation, a single responsible party is not enough. Continuity assurance rests on three complementary pillars. The first is deterministic application monitoring of queues and API gateways. The second is probabilistic quality monitoring of data drift and extraction accuracy. The third consists of formal interventions through runbooks and escalation routes. These components serve different purposes: tracking availability, identifying deviating output and establishing who acts when a deviation occurs.
The external dependency makes this three-part division visible. A technical outage or rate limit may be a direct availability issue. A changed model outcome, by contrast, may combine technical reachability with a less usable substantive outcome. A runbook and escalation route connect both situations to a decision about the process step. This creates a place for the question of whether the AI component should be interrupted, investigated or put back into use, rather than merely generating an alert about an external API.
An architecture with automated fallbacks can support process availability when an external provider changes or imposes limits. Their presence does not remove the ownership issue. Someone must still determine which fallback is acceptable in the process context and when a deviation counts as an incident. Especially when the technical chain offers alternatives, a formal decision on substantive acceptance remains necessary.
Ownership therefore requires the most explicit elaboration where autonomy, external dependency and process consequences converge. This is where application monitoring, quality control and formal intervention meet; an unclear boundary between these responsibilities delays the response when normal processing is under pressure.
Sources for this section: NIST AI Risk Management Framework (AI RMF 1.0)
Key factors in allocating ownership
The allocation of ownership determines not only who receives an alert, but also how the process balances processing speed, human control and formal change discipline. The comparison below shows the consequence of each choice for AI-supported processes.
| Factor | Trade-off in the choice | Meaning for ownership |
|---|---|---|
| Processing speed | Automated straight-through processing supports fast throughput. Human validation interactions in edge cases add control overhead and staffing costs. | The role that accepts the process outcome must determine when speed takes priority and when an edge case requires human review. This choice is functional: it concerns the acceptability of processing, not only the availability of the technology. |
| Control in edge cases | A human validation step can catch deviating situations, but makes processing less uninterrupted and requires employee involvement. | Ownership must establish who performs or accepts the validation interaction and who is authorised to change the boundary between automatic processing and human review. Otherwise, a deviating outcome is treated as a technical issue when the question is actually about process control. |
| Room for experimentation | AI encourages experimentation and innovation. In processes with significant operational consequences, this is balanced by governance friction. | A formal allocation of roles makes it clear who may decide on changes that move from an experiment to regular process processing. This does not necessarily limit the use of AI, but makes the transition to a formally managed application explicit. |
| Formal governance | RACI matrices, release audits and change approvals take time and add steps to changes. | These activities establish who performs, who bears final accountability, who is consulted and who is informed. In AI, this prevents a release or change from entering a core process without a clear party responsible for the substantive consequences. |
| Staffing | More human validation reduces the degree of automated processing and incurs staffing costs; less validation shifts the weight towards automated decision-making. | The allocation should make the staffing consequence visible. The business unit carries the trade-off regarding staffing within the process, while formal governance establishes how that trade-off affects changes and controls. |
Sources for this section: NIST AI Risk Management Framework (AI RMF 1.0)
A practical framework for ownership in AI processes
A useful framework starts with the distinction between a technically green dashboard and a substantively healthy process. Record the allocation of roles in a RACI matrix around the AI decision points themselves, and link that matrix to an explicit escalation route. The following elements give this allocation an operational form.
- Make AI output a separate control point in the RACI matrix. Conventional Laravel applications generally fail deterministically, for example through HTTP error codes or database time-outs. AI systems can fail probabilistically and silently: a successful technical response may still contain hallucinated content or content that deviates from the quality standard. The RACI matrix therefore needs roles for assessing substantive output in addition to roles for technical signals. This establishes who is responsible for assessing deviating AI output and who is informed when that assessment leads to an incident.
- Allocate monitoring according to what it can actually demonstrate. The weather-dashboard illusion arises when dashboards show only server statistics such as CPU, memory and HTTP statuses. Such a dashboard can remain green while the core process fails substantively due to incomplete or hallucinated responses. In the framework, technical monitoring has a clear task: providing visibility into the technical state. In addition, quality monitoring has a separate responsible party who determines whether output continues to meet the quality standard. This separation prevents a green technical picture from being read as the final assessment of the process.
- Make the escalation route a process route, not a forwarding mechanism. A substantive deviation must be able to lead to a recognisable route from signalling to assessment and intervention. The matrix identifies who acts on a technical signal, who assesses process quality and which role is involved when AI output is not acceptable. An escalation then has a predetermined recipient and decision point, rather than becoming an open question between IT and the business unit once consequences become visible.
- Link the authority to interrupt to the substantive assessment. Because technical availability and usable output can diverge, a quality incident requires a formal option to interrupt the AI step in the process. The party responsible for technical follow-up investigates the technical context; the role that safeguards the substantive standard determines whether the AI output can still be used. This keeps the intervention tied to the process quality requirement rather than to whether a server statistic turns red.
Sources for this section: NIST AI Risk Management Framework (AI RMF 1.0)
Frequently asked questions about ownership in AI processes
When choosing between an external AI service and a custom integration layer, two questions recur in particular. The answers relate to the desired degree of process control and to what is contractually established about management.
- Why can IT not be the sole owner?
IT can manage the technical side of an integration, but the choice of integration approach goes beyond technical availability. Ready-made external SaaS or LLM APIs can offer a short time to market. On the other hand, a custom integration layer in Laravel can provide greater data control, deterministic fallback control and continuity assurance. The trade-off therefore also concerns which outcome and which interruption of the process are acceptable. These are questions that cannot be answered solely by the technical management role. The business unit understands the meaning of the output within the process; IT can manage the technical consequences of the chosen integration approach. Dividing ownership prevents both questions from being assigned to one role without that role having all relevant information. - Which elements belong in an SLA for an AI process?
The available starting points do not prescribe a fixed set of SLA elements. They do show that an SLA alone is not a replacement for an explicit allocation of responsibilities. With external API dependency, the distinction between rapid adoption and control over continuity is relevant. Demonstrable architecture expertise can be expressed through robust fallbacks, asynchronous Laravel Queues and circuit breakers, enabling the core process to remain operational during external API outages. For contractual agreements, this means that the organisation must first be clear about which continuity role it expects from the chosen integration approach and who is accountable for it. Without this prior allocation of roles, an SLA remains an availability agreement without a clear answer to who decides on process consequences.
Sources for this section: NIST AI Risk Management Framework (AI RMF 1.0)
Key considerations for AI continuity ownership
The usefulness of an ownership model after launch is not shown by job titles, but by whether a quality deviation can be quickly recognised, assessed and contained. Three concrete checkpoints show whether the responsibilities for this have actually been assigned.
- Is every role around source data, monitoring, incident escalation and bug fixing explicitly assigned?
A concrete RACI and Operating Model matrix makes this allocation visible from the outset. It distinguishes between the party managing source data, the party tracking signals, the role escalating in an incident and the party fixing an error. The model does not prevent deviations from occurring, but it limits the time lost determining who may or must perform the next action. It also makes clear to the business owner where their own responsibility begins and ends. - Does monitoring give the business owner sufficient insight into the process outcome?
Integrated management and observability dashboards can provide real-time insight into token budgets, error margins, response times and audit trails of input and output. This combination supports a discussion of costs and technical throughput as well as the traceability of what the AI component has processed. A dashboard is not a replacement for an owner; it provides the information with which that owner can determine whether a deviation has operational consequences. - Does an incident route lead to a decision that can limit further consequences?
An escalation path has value only when it is linked to a role with concrete authority. The route must therefore result in a decision about continuing the AI step, alongside technical follow-up of the cause and assigned bug fixing. This connects the RACI allocation to day-to-day management: source data, signalling, assessment and recovery are not treated as separate activities. When this decision point is absent, incorrect output can continue causing financial or operational consequences while teams are still determining who is responsible.
Sources for this section: NIST AI Risk Management Framework (AI RMF 1.0)
