Optimization is preferable to a full rebuild when the slowdown in development is primarily caused by maintenance-sensitive parts of the application. If targeted improvements eliminate the need to repeatedly work through fragmented code, the existing foundation can be retained while pressure on feature delivery decreases.
Costs and risks in Laravel modernization
When modernizing growing Laravel web applications, it is essential to compare the costs and risks of emergency fixes, optimization and rebuilding. These choices affect not only the development budget, but also operational continuity and strategic opportunities.
- Optimization is suitable when delays mainly arise from specific maintenance-sensitive parts of the application.
- Emergency fixes can lead to higher costs due to repeated deployment and disruption of regular processes.
- Planned modernization, such as through the Strangler Fig pattern, provides a controlled approach without operational interruptions.
- A full rebuild may seem attractive, but it carries risks of scope expansion and duplicate maintenance costs.
- The choice between optimization and rebuilding must account for the balance between short-term speed and long-term stability.
When optimization takes precedence over rebuilding
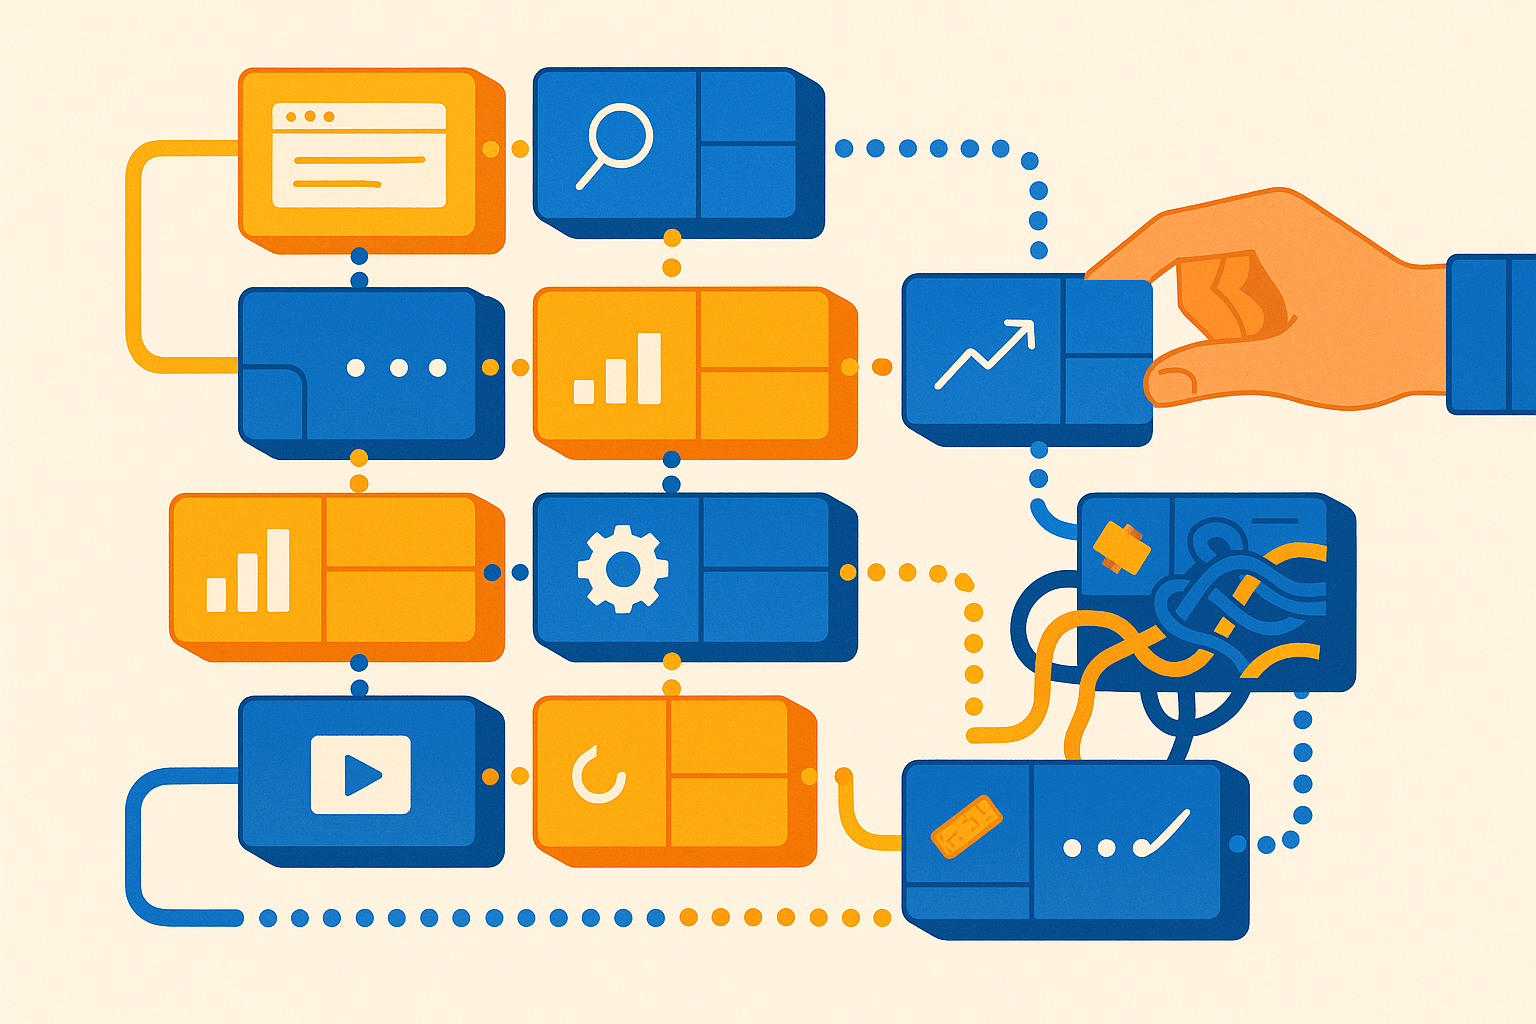
The line between optimizing and rebuilding is not determined by the age of a Laravel application, but by the cause of the slowdown. Technical debt acts as a recurring levy on every change: developers must navigate fragmented and repeatedly modified code before a feature can be adjusted or added. As a result, the speed at which new functionality becomes available declines. That delay is a relevant signal, but not independent proof that the entire application needs to be replaced.
Optimization is more appropriate when the obstacle is visibly concentrated in parts of the application that generate substantial change work. This could, for example, be a component where database connections are exhausted, where Database Lock Contention occurs, or where lagging processing causes Backpressure. The business question is then not whether all existing code looks modern, but whether the delay can be traced back to a limited number of maintenance-sensitive components. If targeted improvement removes the need to repeatedly work through the same fragmented or patched code, the existing foundation remains usable while pressure on feature delivery decreases.
This approach prevents an organization from making a replacement decision based on inconvenience alone. A growing application can contain valuable business logic while still having an expensive path for making changes. The technical debt then lies in the way modifications move through the codebase, not automatically in the full functional scope of the application. The investment can therefore be focused on the components that actually slow down change work.
The practical test is whether an intended improvement makes future changes less dependent on untangling fragmented code. If that is unlikely, further investigation into a broader intervention is more appropriate than another round of optimization.
Sources for this section: legacyleap.ai, martinfowler.com
Why emergency fixes can be more expensive than planned work
At first glance, emergency fixes appear efficient because they focus on resolving acute disruptions immediately. In practice, however, they require repeated deployment of resources: every time an incident occurs, developers and operations teams must intervene under time pressure. This leads not only to direct costs, but also to disruption of regular processes and postponement of planned work. The organization consequently becomes increasingly dependent on ad hoc solutions, causing structural improvements to be deferred and technical debt to accumulate further.
The cost difference can be significant: according to the available comparison, ad hoc emergency work can be four to ten times more expensive than comparable planned work. That difference becomes easier to understand when an outage does not stand alone. A cache avalanche, for example, can place additional pressure on the database, while insufficient Backpressure in a message stream allows backlogs to grow. Under time pressure, the team must then simultaneously limit the direct disruption, assess the consequences for other components, and interrupt regular work.
Planned modernization, for example through a phased approach such as the Strangler Fig pattern, makes it possible to replace components of a monolithic application in a controlled manner without interrupting operational continuity. By gradually placing new or modernized components behind a routing layer, the existing application remains in use while modernization progresses. This creates room to assess dependencies and error handling, for example with Circuit Breakers, outside the pressure of an incident.
The core of the comparison is therefore control over work: emergency fixes repeatedly disrupt planning, while a modernization path makes maintenance and replacement plannable. For growing Laravel applications, that predictability may outweigh the seemingly limited scope of individual patches.
Sources for this section: martinfowler.com, techment.com
When does the comparison between optimization and rebuilding become relevant?
The comparison between optimization and rebuilding becomes concrete as soon as an organization faces not only a technical backlog, but also an execution decision. A full rebuild may then seem straightforward: the existing system will eventually disappear and a new foundation will take over everything. That appeal can be misleading when the scope of the new work continues to grow during the process.
In a full rebuild, scope expansion can make the program increasingly burdensome. New requirements, uncertainties that become visible only during replacement, and components that still need to be included increase the gap between the original plan and the actual delivery. At the same time, the existing system remains in production and requires maintenance as long as the replacement is not ready.
That duplicate maintenance is the central cost and risk factor in rebuilding. The organization funds work on a new system while keeping current services operational. A decision to rebuild should therefore not focus solely on the appeal of a clean start, but also on whether the scope remains manageable throughout the transition.
Optimization is a viable option in this situation when a full rebuild is mainly being considered due to dissatisfaction with the current state, without the consequences of scope expansion and parallel maintenance being bounded. Rebuilding remains possible, but requires an executable path alongside the running system.
Sources for this section: intertec.io
Comparison of costs and risks between patching, optimization, and rebuilding
The three paths mainly differ in the extent to which they keep the execution of changes manageable. The comparison below distinguishes patching, optimization, and rebuilding without suggesting that any one path is without costs or risks.
| Path | Cost and risk profile | Impact on delivery and strategic flexibility |
|---|---|---|
| Patching | The direct intervention may be limited, but the underlying problem remains when the same vulnerability repeatedly returns. In the case of Thread Pool Starvation or a recurring capacity issue, a patch can easily shift analysis of the cause to the next incident. | New functionality may become available later because capacity is once again redirected to recovery work. The costs then lie not only in the patch, but also in interrupted planned work. |
| Optimization | Optimization focuses on the conditions under which changes and releases take place, for example by specifically addressing bottlenecks in dependencies or processing. The available information does not provide a fixed cost ratio, but it does provide reason to weigh the impact on operational risk. | A more manageable path to delivery can limit delays in desired innovation. This is relevant, for example, to a B2B customer portal or a new API integration. |
| Rebuilding | A rebuild requires an independent assessment of investment, lead time, and execution risk. As described earlier, scope expansion and parallel maintenance remain relevant burdens for as long as the transition continues. | The strategic value depends on when the new capabilities actually become available. If desired innovations are postponed by months, opportunity costs arise relative to competitors. |
Sources for this section: viitorcloud.com, martinfowler.com
Trade-offs between short-term speed and long-term stability
The tension is often not between useful and unnecessary work, but between two different forms of value competing for the same capacity.
- Short-term feature speed: Directly visible commercial features may understandably take priority because they quickly address a specific demand from the market or operations. The downside arises when architectural improvements are structurally postponed. Technical maintenance then remains outside the plan until problems emerge as incidents. The initial speed is therefore not cost-free: it shifts work to a later point when circumstances are less manageable.
Long-term stability: Architectural improvements do not always deliver immediately visible functionality, but they are intended to reduce the maintenance pressure that may later lead to disruption. This choice also has a cost, because capacity is temporarily not directed toward commercial features. The relevant consideration is whether postponing maintenance creates a risk of incidents and downtime that outweighs the value of immediate feature delivery. A plan that explicitly places both types of work side by side makes the consequence of postponement visible.
Sources for this section: martinfowler.com, staffordwilliams.com
Frequently asked questions about modernizing Laravel applications
The questions below focus on managing risks during the modernization of Laravel applications, emphasizing methods that enable incremental change.
- How does the Strangler Fig pattern work in modernization?
The Strangler Fig pattern enables a phased migration in which existing parts of a Laravel application are gradually replaced. This starts with an audit and the creation of a roadmap. Individual components are then migrated, with each step supported by automated testing, validation in a staging environment, and predefined rollback scenarios. This approach keeps the application operational and manages risks at each migration step, rather than implementing all changes at once. - What are the risks of a big-bang rebuild?
A big-bang rebuild brings all changes together at one moment, making it more difficult to isolate and roll back individual errors. This increases the likelihood of disruptions and makes it harder to maintain control over progress and quality. By choosing a phased migration methodology, such as the Strangler Fig pattern, organizations can validate and adjust at each step, better safeguarding the application's manageability and continuity.
Sources for this section: martinfowler.com, techment.com
Key considerations for modernizing Laravel applications
The decision to modernize gains more support when it is treated as an allocation of scarce capacity between visible growth and the management of operational risk.
- Make the costs of postponement visible. Not every technical improvement requires immediate implementation, but structural postponement has its own financial profile. Directly visible commercial features compete with architectural improvements that are less immediately noticeable. The financial comparison should therefore include not only the budget for the modernization initiative, but also the recurring costs of recovery work and interrupted planning when maintenance is deferred.
- Assess risk as a continuity issue. The relevant question is not only how much work a change requires, but also what consequences disruption has for daily operations. Downtime is an operational risk directly related to maintenance choices. A path that reduces maintenance pressure therefore has value in addition to the function it delivers technically.
- Link strategic fit to feature planning. A commercialization or growth plan often calls for visible functionality. At the same time, that planning affects the decision whether or not to include architectural improvements. The assessment is stronger when the organization identifies which features are needed now, what maintenance burden is accepted for them, and when that burden will still be addressed. This makes the sequence of investments explicit.
- Reassess the trade-off when circumstances change. The relationship between feature delivery and maintenance shifts as incidents, downtime, or commercial priorities change. A modernization decision therefore remains connected to current capacity and the costs of postponement. This keeps maintenance as part of planning, rather than work that receives attention only after a disruption.
Sources for this section: martinfowler.com, staffordwilliams.com