
Regulated organisations can define a phased managed services scope by mapping the complete dependency chain of critical business functions. This ensures interconnected components fall under the same oversight and security classification, while systems that follow later are documented with clear boundaries and responsibilities in advance.
Scoping Managed Services in Regulated Contexts
Defining a phased scope for managed services in regulated environments requires careful consideration of technical dependencies and operational responsibilities. This prevents compliance gaps and operational disputes.
- Identify all technical dependencies of critical business functions to determine which systems must be included in the first phase.
- Ensure a clear separation of responsibilities and authority between the managed services provider and internal teams.
- Document which systems are deliberately moved to later phases and which control measures apply to them.
- Differentiate service levels and escalation times based on system criticality to avoid uniform response times.
Why a clear scope is essential for managed services
A phase 1 managed services scope is more than a list of applications a managed services provider may touch. In a regulated operation, that boundary determines which parts of the landscape fall within operational responsibility, which dependencies are involved and which situations have a response path. If that boundary is drawn solely around visible applications, the actual operation of the service may remain out of view. This does not create an abstract documentation issue, but practical uncertainty when a disruption occurs.
The technical architecture of the application landscape determines how sharply that boundary can be drawn. In a modular landscape with decoupled APIs, individual services can, under certain conditions, be placed separately in phase 1. The boundary can then align with a specific service and its associated interfaces. In a monolithic landscape with shared databases, this is different: the central data layer connects components in such a way that including only one application component can become an artificial boundary. For the scope, this means the central data layer must be considered at the same time when it forms the shared foundation. The phase 1 choice therefore follows not only from a system's visibility or popularity, but also from how systems technically depend on one another.
A second distinction concerns the weight of the operational response. When secondary internal tooling receives the same escalation procedures and service level as applications for order processing or patient data, intervention capacity is allocated as if every incident has the same consequences. As a result, genuine emergencies may receive attention more slowly. A clear scope therefore makes visible which category of systems requires which response. The objective is not to treat every system equally, but to focus limited attention on the components with the greatest operational significance.
Technical interdependence and the required response therefore belong to the same boundary. By establishing both in advance, the scope remains usable when pressure is greatest and differing expectations between internal teams and the managed services provider are limited.
The challenges of defining a managed services scope
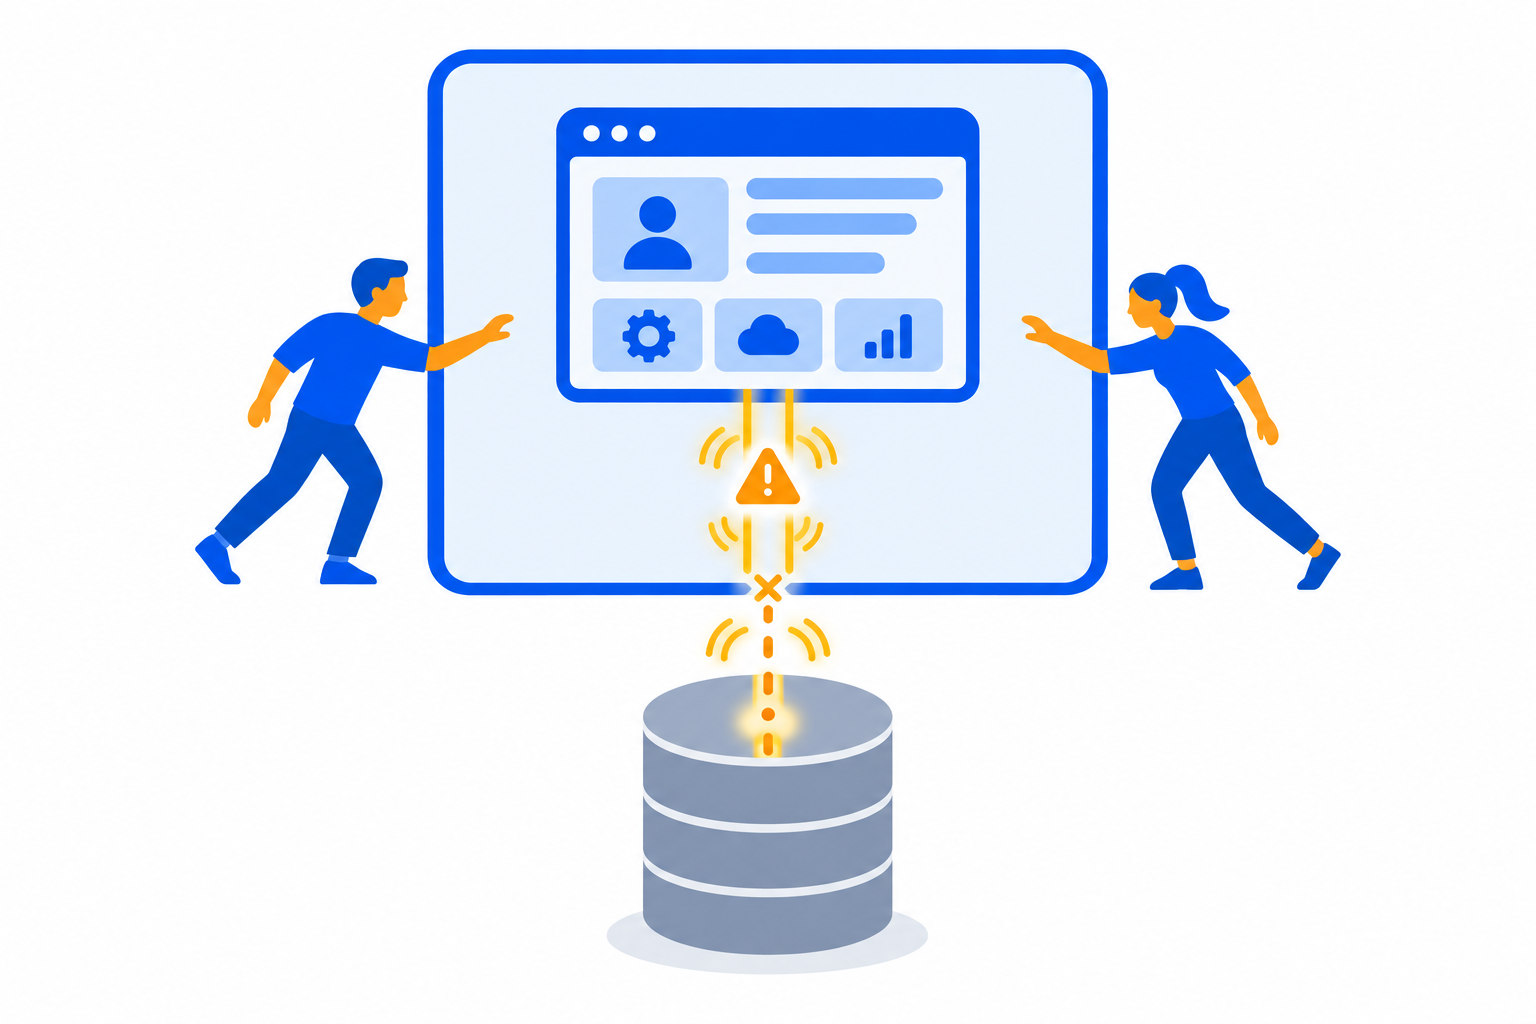
The most difficult mistake in scope definition is often not that an organisation names too few systems, but that it treats a service as independent when it actually depends on layers outside the engagement. A web portal, for example, may be the visible starting point for users. Its operation may, however, depend on an underlying database. If only the portal is brought under management, part of the technical chain remains outside the agreed responsibility.
This becomes apparent as soon as disruptions occur that manifest as delays or API errors. The managed services provider cannot properly investigate such symptoms when the relevant dependency lies outside its access and responsibility. Internal management, in turn, has a limited starting point when the behaviour is primarily visible in the portal. Without documented interdependence, the question quickly shifts from cause to owner: does the problem lie with the managed portal, the underlying database or the boundary between them?
This lack of clarity affects incident response. Teams spend time defining their role while an operational disruption continues. Escalation may therefore stall, not because technical knowledge is unavailable, but because it has not been established who owns the investigation and follow-up. In a regulated environment, such a delay has an additional dimension: an operational incident can escalate into a compliance breach when the chain is not brought under control in time.
A scope that lists only functional names provides too little guidance for this scenario. In addition to determining whether the portal falls within phase 1, it must therefore be clear which components are needed to assess and resolve an incident. The scope then functions as an operational boundary: it describes what the managed services provider can investigate, where internal management remains responsible and how an incident is handed over.
When is a phased approach necessary?
A phased approach to managed services may be necessary when organisations are subject to frameworks such as DORA or the EBA Guidelines while also needing to retain operational continuity and control over critical functions. In many supervisory regimes, it is not sufficient to introduce management step by step without safeguarding the relevant conditions from the outset. When outsourcing applications that support critical functions, contractual audit rights, exit arrangements and incident reporting generally form part of the control arrangements. Formal agreements and oversight mechanisms therefore do not need to wait for a later technical or organisational phase.
Phasing is particularly appropriate when the IT landscape is complex and not all systems or processes can responsibly be transferred at once. A clearly delineated first phase keeps the transition manageable while also making visible which components have not yet been transferred and how incidents and reporting are handled for them. Phased implementation therefore does not change the need to arrange oversight, reporting and transferability for systems that support a critical function.
Key criteria for phase 1 inclusion
Phase 1 is the first explicitly delineated management scope within a phased transition. The duration and number of subsequent phases differ by organisation; the determining factor is which systems and activities fall under the management arrangements from the outset. In making that choice, it is essential to look beyond visible core applications alone. The following criteria help prevent compliance-critical components from unintentionally falling outside the scope:
- Identify all necessary prerequisites for each core application. Check whether supporting components such as SSO identity providers, DNS configurations and SSL certificate management have been explicitly included. These provisions may sometimes seem generic, but in practice they are decisive for the application's availability and recoverability.
- Assess whether each prerequisite has a direct operational impact on access or continuity. If the failure of a prerequisite directly prevents an application from being used or restored, it belongs within the phase 1 scope, or a clear owner with authority to intervene outside the managed services provider must be designated.
- Document who assumes management and incident handling for each excluded component. This assignment prevents the need to first determine which party is authorised to intervene during a disruption.
The test is practical: can the application remain available, accessible and recoverable within the chosen boundary? If the answer is no, the phase 1 scope requires expansion or an explicit external management arrangement.
A structured approach to scoping
A structured approach to determining the phase 1 scope of managed services starts with the business function central to the outsourcing arrangement. This prevents essential technical components from being overlooked because they are less visible in day-to-day operations. The following steps help avoid compliance gaps:
- Map the complete dependency chain of the selected business function. Fault isolation and dependency mapping reveal which software components directly contribute to the critical function. Components that are functionally connected must be included in the same oversight and security assessment. Administrative boundaries alone are not a reason to place them outside the phase 1 scope.
- Work from function to component, not the other way around. Start by establishing the business function that cannot be viewed separately from the start of management. Then identify the supporting components and explicitly document how each component contributes to the function. This makes the relationship between function and component clear, including for teams not involved in the original scope definition.
- Document which components are deliberately deferred. A component can be moved to a later phase if the dependency analysis shows that it is not essential to the selected function. If a functional connection does exist, deferral requires additional control measures. The deferral decision therefore remains assessable rather than implicit.
Frequently asked questions about scoping
A recurring question is whether a managed services proposal cannot be kept simpler by using broad wording. Particularly for work outside the standard service, that simplicity later leaves room for differing interpretations.
- “Does managed services mean that all work related to an application is included?” Not without an explicit description. Transparent delineation in a proposal means that the managed services provider also specifies what falls outside standard managed services. Ad hoc data corrections and bug fixes in legacy systems are examples of work that may be excluded separately. This statement is not a formality, nor is it an indication that such work cannot occur. It makes clear that the normal management engagement and exceptional or additional work are different categories. An organisation can therefore determine in advance who assesses a request, which party performs it and how the transition from management to additional work is handled. The question is then not first asked when an incident, correction request or error message is already creating pressure. It also prevents a broad promise of complete relief from being read as an unlimited obligation. A managed services provider can perform operational tasks within the agreed scope, while data corrections or legacy bug fixes remain outside that standard scope. Both positions are defensible if they are specifically established in advance. When assessing a proposal, the list of included services is therefore not the only relevant element. The list of exclusions is at least as clarifying, including the description of the type of work it covers. That list also gives involved teams guidance when they did not participate in the original contract discussion.
Key considerations for a safe start
Exclusions, however, only describe which activities do not belong to the standard service. To prevent this from still leading to role confusion in a specific request, it must also be established for each activity who acts, decides and is informed.
The first management phase is only manageable when not only systems, but also roles for each activity, are clearly defined. This requires a document that remains usable under operational pressure and does not serve solely as an attachment to a proposal.
- Request a detailed RACI matrix in which execution, advice and oversight are separated. Such a matrix makes clear for each subject who is responsible for execution, who is accountable for it, who is consulted and who remains informed. For a phase 1 scope, this distinction has particular value because operational execution is not the same role as advising on a decision or overseeing its execution. If these roles overlap, one party may assume another party will act, while that other party only has an advisory or supervisory position. The matrix makes the transition from question to action visible: which party performs a management task, which decision carries formal responsibility, which party provides substantive input and who receives information about progress or an incident. New activities can also be assessed more specifically this way. Not every request related to a managed system must automatically be performed by the same party; the allocation of roles shows whether it concerns execution, advice or oversight. For an organisation implementing managed services in phases, this reduces the risk that an unexpected task develops into a discussion about mandate, resources or costs after the situation has already arisen. Without an assigned executing role, an activity does not belong to the operational managed service delivery.